
Technical SEO / 9 min read
The technical SEO problems that actually cost money.
An audit finds 600 warnings. Your developer has time to fix six. Which six? The honest answer depends on what is stopping customers from finding your important pages or using them, and almost nothing in a default audit report is sorted that way.
A missing product category costs more than a slightly long meta description. A broken mobile enquiry form costs more than a perfect performance score. The problems worth fixing first are the ones preventing valuable pages from being discovered, indexed, understood or used. Everything else needs a business case before it takes anyone's time.
This is the order we work in, adjusted by whatever the evidence on a particular site says.
| Priority | Problem | Commercial consequence |
|---|---|---|
| 1 | Important pages unavailable, excluded from indexing, or pointing at the wrong canonical | The page never gets a chance to attract search traffic at all |
| 2 | Essential content or navigation missing when Google renders the page | Products and services become harder to discover or understand |
| 3 | Large volumes of unnecessary URLs interfering with crawling | New or updated pages take longer to be processed |
| 4 | Duplicate URLs and unwanted pages appearing in search | Customers reach the wrong version; maintenance gets inefficient |
| 5 | Slow or unstable pages | Visitors struggle to browse, enquire or buy |
A severe performance problem can jump straight to the top. This is a working order, not a universal ranking of financial loss.
Crawl budget, and who actually needs to care
Two different things get confused here constantly. Crawling is Google fetching your pages. Indexing is Google deciding whether to store and use what it found.
Crawl budget is roughly how much crawling Google can and wants to do on your site. It is not an allowance you buy, and not a score to maximise.
Most small business sites do not need a crawl budget project. If your important pages get discovered promptly and your updates are processed within a reasonable time, look elsewhere first. Google's guidance on the subject is aimed mainly at very large sites, sites with a lot of rapidly changing content, and sites carrying many URLs stuck at "Discovered — currently not indexed".
It becomes worth investigating when valuable pages sit undiscovered while Google repeatedly fetches pointless URL variations. Check server reliability at the same time, because recurring errors and slow responses interfere with crawling on their own.
A page missing from search does not prove you ran out of crawl budget. It might be duplicated, deliberately excluded, poorly linked internally, or simply not considered useful enough to store.
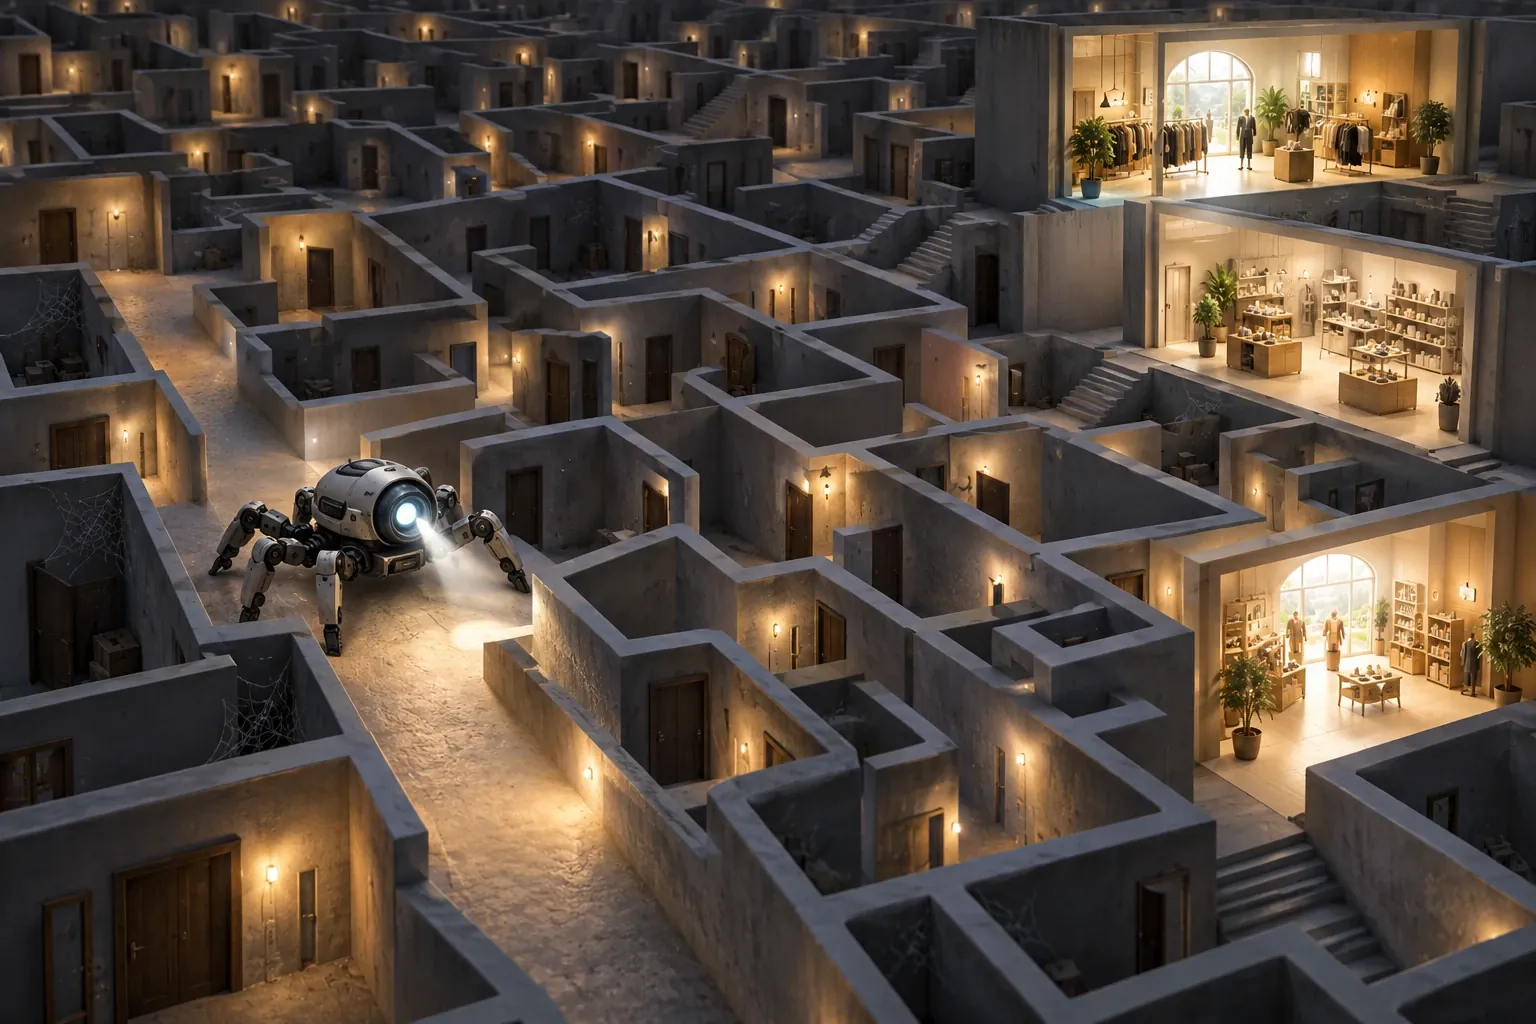
How 200 real pages become 40,000 crawlable URLs
A category offers filters for colour, size, material, price and availability. Add sorting, and add the fact that parameters can appear in any order, and one collection now has thousands of addresses.
- /chairs/?colour=blue
- /chairs/?colour=blue&material=wood
- /chairs/?material=wood&colour=blue&sort=price
Some of those combinations deserve to be landing pages, because people genuinely search for them. Most repeat almost identical results, or return nothing at all.
The cost appears when Google spends real effort fetching variations while your actual products wait. Worth being careful here: the number 40,000 does not by itself prove anything. You need crawl evidence and delayed discovery to support the diagnosis, or you are about to spend development budget on a problem you have not confirmed.
Good faceted navigation separates useful search destinations from browsing controls. Keep valuable filtered categories accessible with stable URLs and real content. Limit crawling of combinations with no search purpose. Make impossible combinations return a sensible response rather than generating infinite empty pages. Google's faceted navigation guidance sets out the options.
Canonical tags help express a preference. They are not a reliable way to control a URL space that is already out of control.
Indexed pages that should never have been
More indexed pages is not more visibility. Common unwanted results include internal search pages holding arbitrary queries, filter combinations with no standalone purpose, publicly reachable staging copies, and near-empty tag archives.
Decide by purpose rather than by type. A well-maintained tag archive that genuinely helps people explore a subject may deserve indexing. A filtered category with real demand behind it may be commercially valuable.
| What you want | The right control |
|---|---|
| Keep a page public but out of search | noindex, and let Google crawl it |
| Protect a staging environment | Require authentication |
| Consolidate genuinely duplicate pages | Consistent canonical signals, or a redirect |
| Stop unnecessary crawling | Carefully scoped crawl controls |
| Remove a page with no replacement | A genuine 404 or 410 |
Blocking crawling is not the same as removing a page from the index. Google has to be able to fetch a page to see its noindex instruction, so blocking it in robots.txt can prevent that instruction being processed at all. Google's documentation is explicit about this. For URLs already indexed, plan the removal sequence before you add any crawl blocks.
Parameters and pagination need different fixes
Tracking parameters create several addresses for one page.
- /services/roof-repairs/
- /services/roof-repairs/?utm_source=newsletter
Sorting, session identifiers and inconsistent URL formatting multiply it further. For genuinely equivalent pages, point canonical signals at the preferred URL, use that version consistently in internal links and sitemaps, then check whether Google actually agrees with your choice.
Ordinary duplicate content is not a penalty. Google's SEO Starter Guide is clear that duplication can create poor experiences and unnecessary crawling without being a spam policy violation. The commercial problem is usually confusion or inefficiency: the wrong page ranks, signals are harder to consolidate, visitors land somewhere unsuitable.
Pagination needs the opposite treatment. Page two of a category contains different products from page one, so do not canonicalise every page in a sequence back to the first. Give each page its own URL and its own canonical, with crawlable links between them. Google's pagination guidance recommends exactly this, and notes that a "load more" button on its own may not give Google a discoverable route to every product.
These problems usually arrive with a platform change. Build URL mapping and indexing checks into your website redesign plan before launch rather than diagnosing them afterwards.
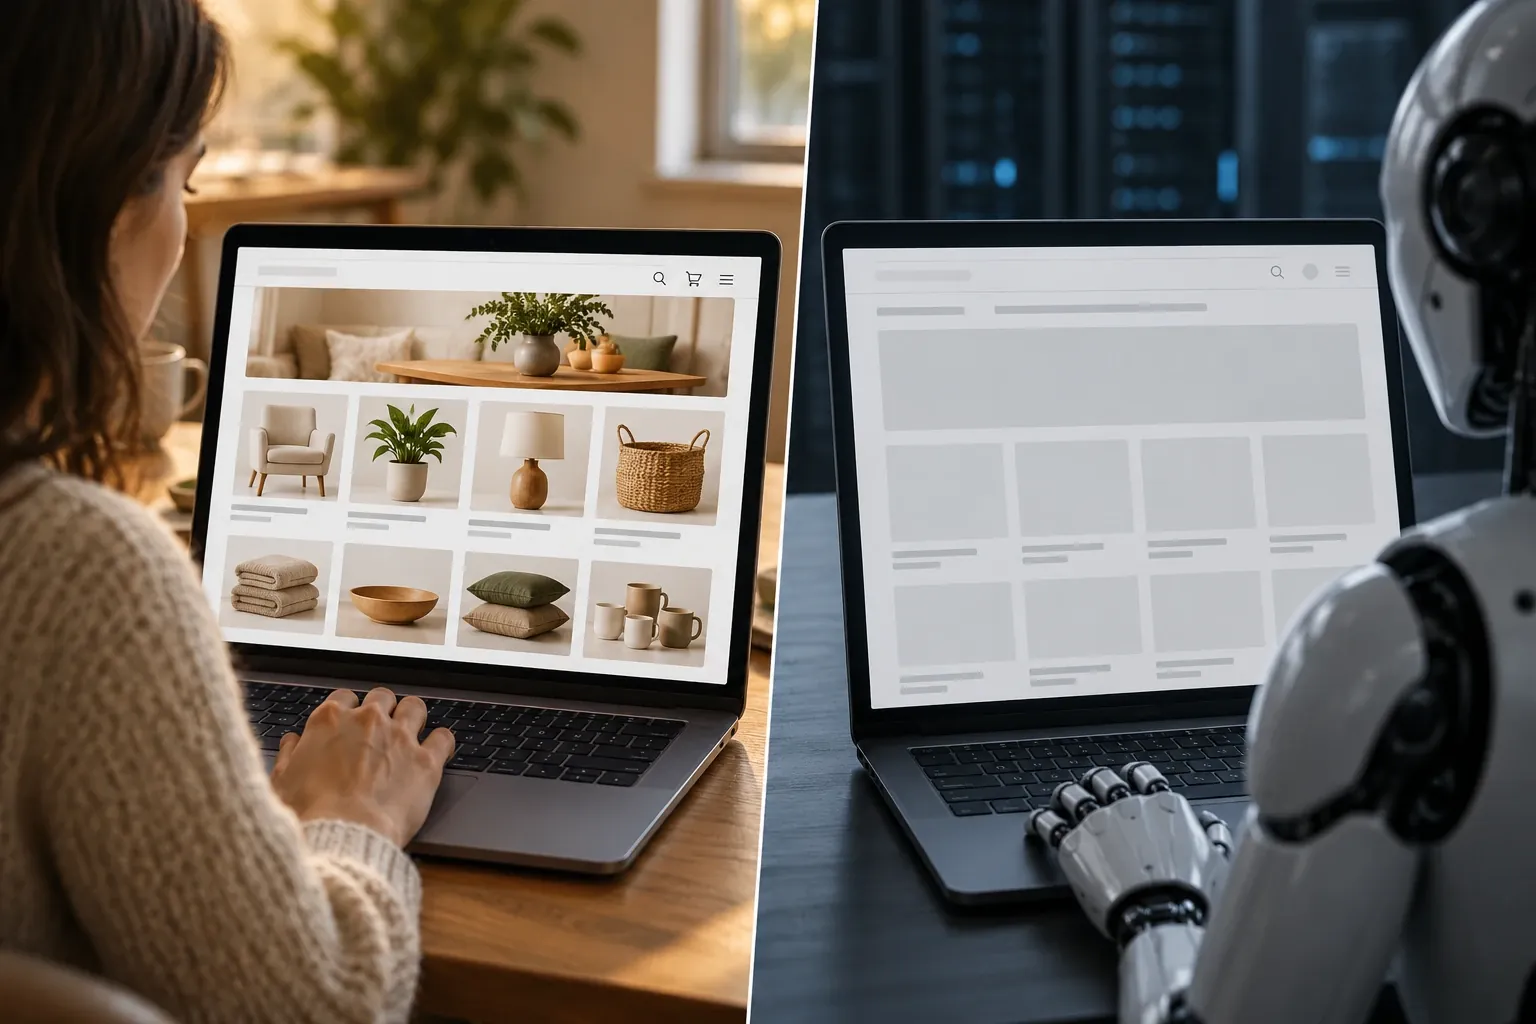
Content Google may never see
A page can look complete in your browser while key content is missing from Google's rendered version. Failed scripts, blocked resources, broken data requests, or content that only appears after someone interacts with the page.
Google can render JavaScript. The question is whether your particular implementation delivers the essential content reliably. For a service page that means the actual explanation of the service. For a shop it means products, descriptions and links through to individual product pages.
Test a representative page in Search Console's URL Inspection tool, run a live test, and read the rendered HTML and screenshot looking for the specific text and links a customer needs. Do not stop at "the page loaded".
Where you can, deliver essential content in the initial HTML through server rendering or pre-rendering, and keep navigation as real links with real destinations. Google's JavaScript SEO documentation covers the requirements.
This moves to the top of the list when one broken template affects every product or service page, because fixing a single shared rendering fault can restore an entire section at once.
Page speed, beyond the score
Core Web Vitals are used in Google's ranking systems, but good scores do not produce rankings on their own. Relevance and usefulness still decide most of it, and Google's page experience guidance explains that relationship plainly.
| Metric | What it measures | "Good" threshold |
|---|---|---|
| Largest Contentful Paint (LCP) | When the main visible content loads | 2.5 seconds or less |
| Interaction to Next Paint (INP) | Responsiveness to interaction | 200 milliseconds or less |
| Cumulative Layout Shift (CLS) | Unexpected movement of page elements | 0.1 or less |
These are assessed at the 75th percentile of visits, with mobile and desktop treated separately. The Web Vitals documentation defines the metrics and thresholds.
A Lighthouse performance score is a diagnostic from a simulated test. It is not a ranking score. Use real-user data to find the affected templates, then lab tests to work out the cause, and remember that missing field data does not mean a page passed.
Prioritise slow product imagery, unresponsive navigation, and layouts that move a button while somebody is trying to tap it. Then judge the work on enquiries and purchases alongside the technical numbers. Moving a score from 96 to 100 needs a far better justification than making a stalled booking form usable.
The warnings that rarely deserve priority
Some audit findings identify opportunities. Others identify a difference from a tool's preferred settings. These should not displace a confirmed commercial problem:
- An arbitrary word count target. A useful page does not become inadequate at 790 words. Google explicitly rejects the idea of a magic number in its Starter Guide.
- A title a few characters over a tool's limit. Check how it actually appears before rewriting it to satisfy a counter.
- Every excluded URL. Redirects, duplicates and deliberately excluded pages are supposed to be excluded.
- Every 404. A removed page with no replacement should return 404. Broken links pointing at pages that still matter are the real issue.
- A less-than-perfect performance score. Investigate the experience, not the last few points.
- Duplicate content described as an automatic penalty. Diagnose the actual indexing or user problem instead.
For any proposed fix, ask three questions: which pages are affected, what consequence has actually been observed, and how will we know it worked? A warning that cannot answer those is not yet a priority.
Diagnosing all of this free in Search Console
You do not need an audit platform to start.
Performance. Find important pages losing clicks or impressions. Compare sensible periods and account for seasonality. A decline is a starting point, not proof of a technical fault.
URL Inspection. Check indexing status, crawl access and the Google-selected canonical, then compare the stored version against a live test. A successful live test does not guarantee indexing. Google documents the tool here.
Page indexing. Look for patterns affecting valuable page types, and separate expected exclusions from unexpected ones. "Crawled — currently not indexed" is a status to investigate, not a diagnosis.
Crawl stats. Examine host availability, response codes and example URLs. Repeated filter URLs justify a closer look, though the examples are a sample rather than a complete log, and server logs give the fuller picture. Google explains the report here.
Sitemaps and Core Web Vitals. Confirm your intended canonical pages are submitted, and identify templates with poor real-user performance.
Search Console shows symptoms and evidence. Browser testing, server logs and your sales data establish cause and commercial impact.
Turn what you find into a short work queue: affected pages, the evidence, the proposed fix, an owner, and how you will verify it. That is what the technical workstream in our SEO service produces, because the best audit is the one that gives your developer a clear next action and explains why it is worth paying for.